
For decades, the internet was built around human attention. People searched, clicked, subscribed, and purchased. AI is now pushing the web toward a different model where machines request information, call tools, consume resources, and act on our behalf.
The next advantage will not come only from better models or more compute, but from access to the experience locked inside companies, expert workflows, physical environments, and failed experiments.
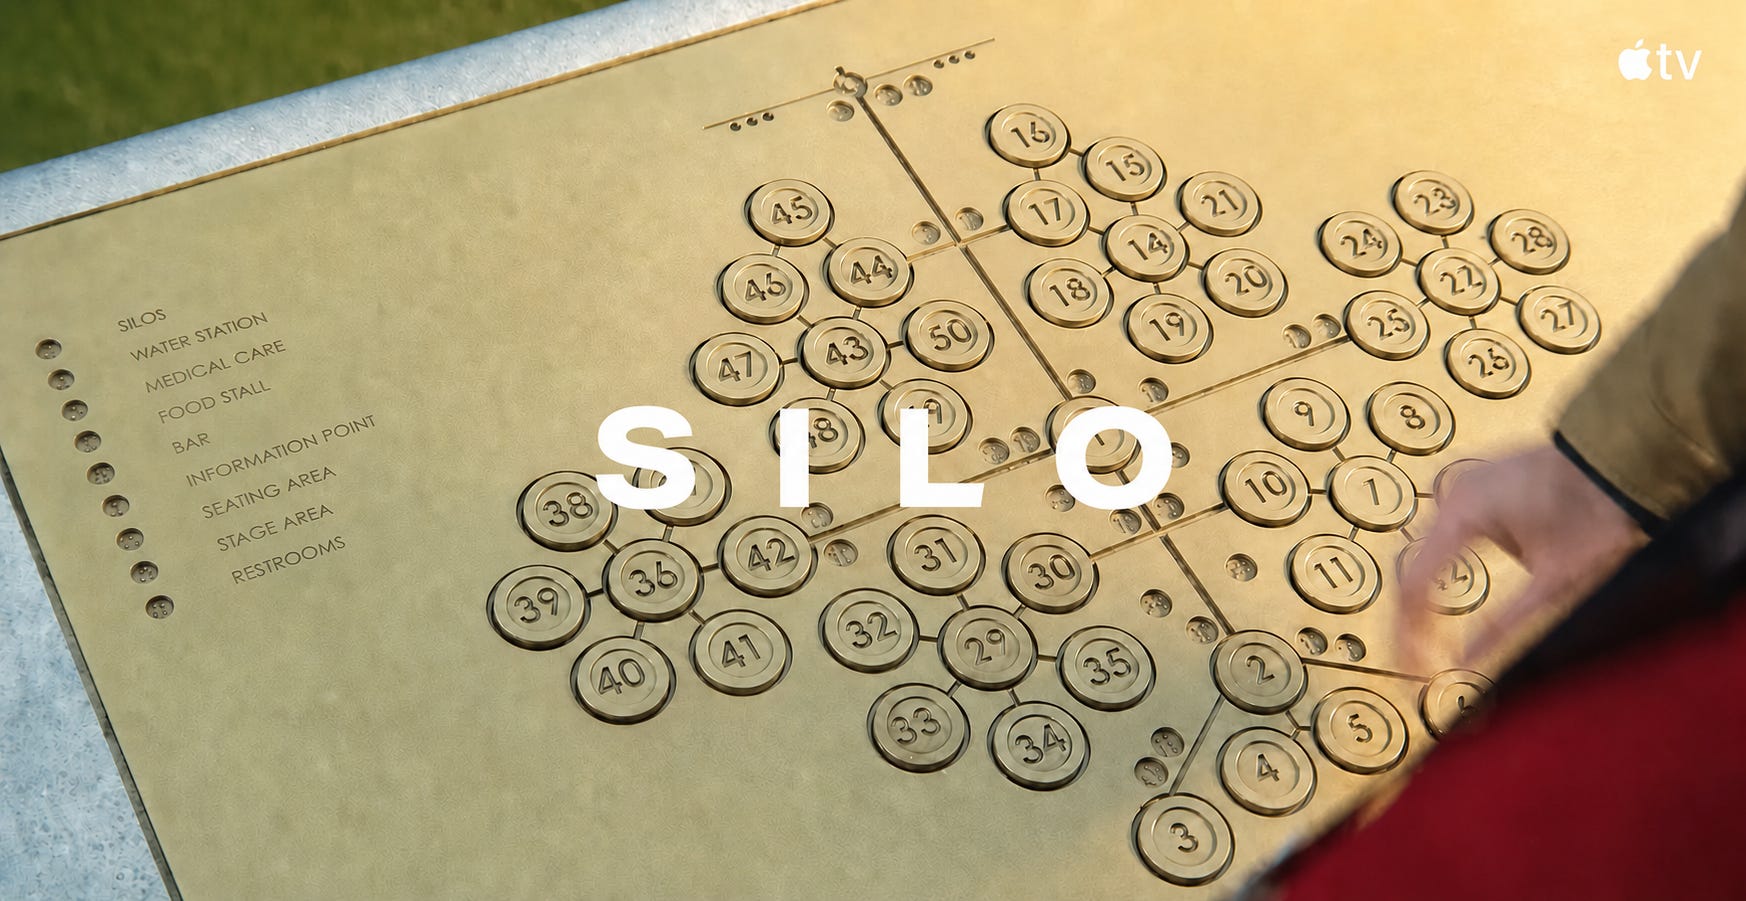
Apple TV’s Silo offers a useful metaphor. Each silo contains its own history and lessons, but those insights rarely travel beyond each silo’s walls. Silos only become stronger when it can learn from what happened in other silos.
This month’s issue explores the infrastructure that could make that kind of learning possible across the internet, from how machines pay for access and how human judgment shapes intelligence to who routes the agentic web and where its next generation of valuable data will come from.
Convergence is brought to you by 321 Converge Inc. (“321”), a new 501c6 created by the founders of The Medici Network.
Sparks ✨
Quick, curated Web2 and Web3 insights you need to know
#1 Why Cloudflare’s Monetization Gateway Matters
Author: Four Pillars

TLDR:
Cloudflare’s recently announced Monetization Gateway lets publishers and developers charge agents through stablecoin-based settlement via x402 (the open payment protocol developed by Coinbase that enables instant, automatic stablecoin payments directly over HTTP) to access webpages, datasets, API requests, and MCP tool calls
AI agents are consuming web publishers’ content without sending back the human traffic that once generated ad, subscription, and purchase revenue — breaking the exchange that made crawling once worthwhile
Cloudflare is turning web access into a programmable pay-per-request system built to monetize agents rather than human visits
Our Takeaway:
Cloudflare began by accelerating the web, expanded into securing and connecting it, and could now help define the commerce layer through which agents access and pay for online resources
The web’s next business model may be less CPM-driven (cost per mille, i.e. impressions) and instead more CPR-driven (cost per request)
None of this would be practical without blockchains and stablecoins, which let agents use x402 to authenticate, make instant micropayments and unlock access without relying on slow, costly financial rails
#2 The Future Worth Building is Human
Author: Thinking Machines Lab (Mira Murati’s, former CTO of OpenAI, AI startup)

TLDR:
AI should bring intelligence to the knowledge and work people already create. Humans should be left in control of what is worth pursuing, what should be built, and how technology should serve meaningful ends
Human participation should not be treated as friction to remove, but an essential input for building AI that continuously improves through human judgement, context, and feedback
AI alignment should be decentralized with different people and organizations able to shape models around their own values, goals, and expertise rather than inheriting a single definition of what intelligence should optimize for
Our Takeaway:
As we leverage proprietary data, local feedback, and organization-specific judgement, future models will diverge beyond today’s frontier models that are trained on much of the same public web
Human-in-the-loop workflows are already emerging across the application stack. Jack Dorsey’s new workplace group chat platform Buzz places humans and agents in the same communication channels. LangGraph lets humans interrupt and approve agent actions during workflows. Omnigent by Databricks provides human teams with a shared environment to review, comment on, and steer live agent sessions
Human-agent workflows need a system of record. One web3 team is building exactly that — Polychrome, the execution layer that runs on top of Makechain, a blockchain protocol storing cryptographically signed audit trails to preserve attribution among human and agent contributors
#3 The Everything Router
Author: Alfonso Gómez-Jordana (Co-Founder of Crossmint)
TLDR:
Stripe is reportedly considering buying OpenRouter for around $10 billion. It’s an option premium over something much bigger than LLM orchestration — increasing the GDP of the internet and increasing their margins on the GDP of the internet
The reported price is difficult to justify on gateway economics alone since gateways are relatively easy to replicate or bundle. OpenRouter was valued at $1.3 billion only months ago, but Stripe may instead be betting on a future where the gateway not only selects the model, but also controls agents’ permissions and connections, calls tools, and completes actions on the user’s behalf
APIs acting on a user’s behalf are not new. Google’s Assistant APIs could complete tasks (e.g. order rides and groceries) as early as 2017, but each action depended on a rigid, hand-built integration. Today’s reasoning models can autonomously choose tools and adapt workflows
Our Takeaway:
Just as browsers shaped how humans navigated the internet, routers will shape how machines act within it by choosing the models, tools, data, and vendors behind each task
Stripe’s recent M&A spree increasingly looks like the blueprint for the financial stack of the agentic web. Bridge.xyz moves stablecoins across borders. Privy gives agents programmable wallets. Metronome measures each unit of AI usage. OpenRouter determines which models and tools are used
Value will likely accrue to whoever controls the transaction path, which may be Stripe’s goal as models commoditize and the surrounding layers compound with every action across routing, authorization, billing, reputation, and settlement
The 3-2-1 🔍
Featured insight breaking down a major story or trend that matters
A Stargate for Data
Author: Will DePue (Ex-OpenAI Engineer)

TLDR:
AI is approaching a shift from compute scarcity to data scarcity. The public internet gave frontier models access to an extraordinary stockpile of text, code, images, research, and human expression. That dataset was created over decades for entirely different reasons, then absorbed by AI as a largely free input. Will describes it as a one-time civilizational subsidy that cannot be repeated at the same scale.
The next wave of useful data will be harder and more expensive to obtain. Much of it sits inside companies, universities, laboratories, governments, physical environments, and the undocumented routines of skilled professionals. It includes failed experiments, difficult edge cases, workflow decisions, expert corrections, and tacit knowledge that was never written down. AI progress will increasingly depend on capturing this missing coverage, not simply adding more compute.
As models move away from the same pool of public internet data, their capabilities may also begin to diverge more sharply. Compute is widely available to any lab able to buy the same chips, but exclusive datasets, custom training environments, and specialized reinforcement-learning tasks are harder to reproduce. The dataset will increasingly determine what a model is uniquely good at, making data one of the industry’s most defensible competitive advantages. For example, it’s no accident that OpenAI is pulling slightly ahead in mathematics and Anthropic in cybersecurity.
The outlook for data businesses is positive, particularly those capable of sourcing niche, expert-generated training material. The closer models get to automating an entire profession, the more valuable the remaining edge cases become. A dataset that produces only a small improvement may still be worth collecting if it closes the gap between a system that handles most of a job and one that can perform it reliably from end to end.
This creates the case for a data effort with the ambition currently reserved for AI infrastructure projects such as Stargate. Data should be treated as a strategic asset on the same level as compute. AI labs may spend tens or hundreds of billions of dollars licensing private datasets, commissioning expert work, creating training environments, and collecting specialized knowledge. The speed at which AI automates science and the economy will be limited by how quickly society can turn unrecorded human knowledge into usable training data.
Our Takeaway:
The coming data boom does not guarantee that data businesses will suddenly become great businesses. Historically, selling static datasets has been difficult because buyers cannot fully judge their value before purchasing them, while the same data may lose much of its commercial value after it has been absorbed into a model. A lab can license a dataset, train on it, and never need to purchase that exact information again. Without a recurring way to produce new and increasingly valuable data, businesses risk becoming a sequence of one-off transactions rather than compounding software companies.
Some of the early winners are companies that can organize scarce expertise and convert it into structured learning signals for AI. Mercor, Turing, and Handshake recruit people with specialized professional or academic knowledge to create training data, evaluate model outputs, and design realistic tasks for frontier models. Mercor generated $614M in gross revenue during the first half of 2026. Third-party estimates suggest Turing’s ARR may be reaching $600-900M+ and Handshake’s to be over $1B. Human judgment and expertise have clearly become a major input market for frontier AI.
The model extends beyond knowledge work and into the physical world. Niantic spent years operating augmented reality and location-based games such as Pokémon Go while building maps and visual-positioning technology grounded in real locations. Its successor, Niantic Spatial, now uses real-world scans and georeferenced data to build large geospatial models for robots, AR devices, drones, and other physical systems. Pokémon Go was not merely a consumer application. It helped create a distributed mechanism for mapping places that would have been prohibitively expensive to collect through a conventional top-down data project. It’s a clear example of how an engaging or useful product can earn the right to collect proprietary real-world data as a byproduct of participation.
As Union Square Ventures points out in their recent Data at the Edge blog post, durable internet businesses have often been built on self-reinforcing data loops. A product collects data, that data improves the product, and the improved product attracts more usage and therefore more data. Falling sensor costs and smarter AI are now extending that loop into previously inaccessible areas such as ambient conversation, the human body, industrial infrastructure, oceans, vehicles, and robotics.
The most valuable data businesses will be built around collection loops, not static datasets. They will operate products, expert networks, or physical systems that continually surface what models still do not know. Mercor, Turing, and Handshake organize human expertise at scale. Niantic turns consumer participation into spatial intelligence. Robotics companies can convert every deployment, correction, and failure into new training material. The strongest businesses will not simply own more data. They will own the mechanism that repeatedly finds rare examples, validates their quality, and feeds them back into a system that improves with use.
Power Quote:
In a data-limited world, economic progress & scientific acceleration will be directly bottlenecked by our coverage in each domain. We need to see data collection as imperative, deserving the same civilizational ambition we’ve given compute.
What We’re Downloading 🎧
Podcasts, interviews, discussions, and research reports that are influencing our thinking
a16z: Why America Needs Clarity with Marc Andreessen and Chris Dixon
David Senra’s Interview of Micky Malka, Founder of Ribbit Capital
Tweet of the Month 🐦
Key takeaways and perspectives from X
Deedy Das (Partner at Menlo Ventures)

Meme of the Month 📸
Send us your memes for a chance to be featured: hello@321converge.com
See you next month,
Nick Tang
X: 0xtangelo
Kris Jenk
X: 0xjinkys
Follow 321 on X @321Converge
Suggest an article or blog post for next month’s Convergence here.